 Alice
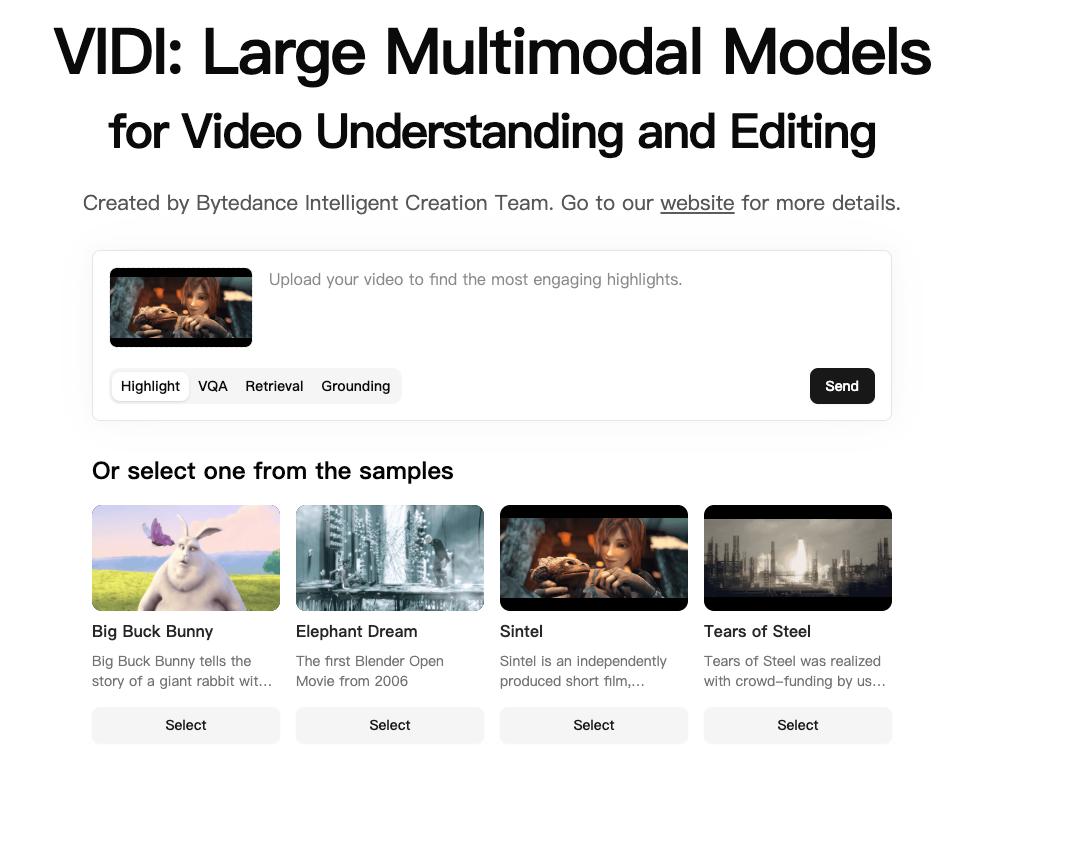
Last week, ByteDance released its latest model, Vidi2, whose core capability is the rapid interpretation of videos — essentially analyzing every frame without human intervention and extracting corresponding data.This is the VIDI2 model.As a product manager, I’ve always been keenly interested in groundbreaking technologies — especially those that, during my PhD research, I hoped would become engineering-driven products with strong technical barriers.A near-revolutionary technology: it changes how we access information.Nowadays, turning WeChat Official Accounts posts into image carousels or videos is already a mainstream form of content creation. But what if we could reverse that process — turning videos back into text? This would dramatically improve the efficiency of content information flow and double humanity’s ability to retrieve information.In the past, we used to say, “Where has someone been?”But now, it’s our ability to access and retrieve information that shapes each person’s worldview.This model will be nothing short of revolutionary for new media creators and influencers.Just like how I — and so many others — now primarily consume information through video, with short and long-form videos dominating the landscape, fewer and fewer people are reading text. As humans, we’re naturally drawn to faster, higher-frequency consumption patterns — the so-called “lazy mode” of media engagement.
Supports Keyword Search in Videos
With Vidi2, you can turn it into a powerful tool for new media — even for educational videos or robotic learning applications. It can extract the narrative and steps from a video in text form, then allow a large language model to compare and memorize the corresponding actions in the video, thereby accelerating model convergence.For example, in the official demo video:
- •You can search for scenes containing a dragon and get a list of matching frames.
- •Input “hand,” and it will output all video segments where hands appear.
User-Acceptable Efficiency: From Text Search to Video Search
With the foundational technology of Vidi2, we can now move toward video-based search, rather than relying on titles.This means clickbait titles will become meaningless, and videos with deceptive thumbnails but unrelated content will no longer work.The focus will finally return to the actual content of the video — including any text within it that can be interpreted.Imagine the vast amount of content on the internet today. To truly find what you need by manually watching videos is incredibly time-consuming — especially when reviewing surveillance footage.But with this technology, you can search inside surveillance videos, quickly locate the exact clips you need, and save massive amounts of time.
Supports Video Element Editing
Beyond search, Vidi2 also enables editing of video elements. Users can search for specific objects and replace them, effectively transforming parts of the video into something else.It’s reminiscent of a sci-fi movie — like Bloodshotstarring Vin Diesel — where a tech company uses video editing to alter the protagonist’s memory by manipulating objects, characters, and even dialogue in video-like reconstructed memories, eventually turning him into an assassin.The scene above shows memory editing, which is akin to spatial intelligence. While Vidi2 currently only supports 2D video, not spatial or 3D video, it’s already powerful enough to double the efficiency of how we access information today.The retrieval speed is now practically usable — far surpassing the experience of watching a short video, let alone sitting through an entire long-form one.
Enforce least privilege outside the model
The model can request a capability, but deterministic policy should decide whether the current identity, resource and arguments are allowed. Tool descriptions are not a security boundary.
Scope credentials to the smallest useful resource set and workflow stage so compromised state cannot reuse broad standing access.
Use short-lived authority
Credentials that expire with the session, task or approval window reduce the impact of leaks and stale workflows. Refresh should require the same policy checks as the original grant.
Where possible, bind tokens to a specific audience or resource.
Test negative paths
Exercise revoked users, expired tokens, replayed requests, cross-tenant identifiers and delayed callbacks. Security controls are reliable only when these cases fail consistently and produce a useful audit record.
Separate identity, policy and credential
A secure system should know who is acting, what that identity may do and which credential proves the authorization to the downstream service. Combining all three in one long-lived token makes rotation and revocation difficult.
Separation also lets policy change without reissuing every identity.
Validate high-impact arguments
Permission to call a tool should not imply permission for every destination, path or amount. Check sensitive arguments against current policy and the user-approved intent before execution.
This prevents a later model turn from widening an action after approval.
Audit the request-to-effect chain
Record who initiated the request, what action was proposed, which rule allowed it and what external effect occurred. High-risk and denied operations deserve stronger retention for investigation.

 admin




