 admin
AI Data Center Networking: Why GPUs Need More Than Fast Chips
Why AI data center performance depends on networking, topology, congestion, storage and collective communication—not GPUs alone.
Why AI data center performance depends on networking, topology, congestion, storage and collective communication—not GPUs alone.

How AI inference autoscaling differs from conventional web scaling across GPU memory, model loading, batching, latency, utilization and capacity planning.
How semantic, prompt and response caching can reduce AI inference cost and latency—and where freshness, privacy and personalization make caching risky.
Why GPU utilization is a critical AI infrastructure metric, and how batching, memory pressure, scheduling and workload shape real economics.
How to calculate AI infrastructure total cost of ownership across GPUs, cloud commitments, power, cooling, networking, utilization, staffing and reliability.
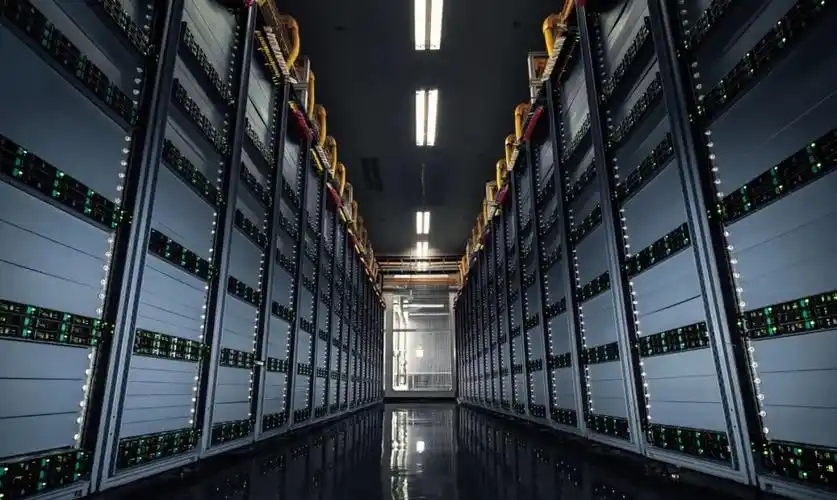
AI data centers are becoming power-and-cooling engineering projects as much as compute projects. Here is how grid access, cooling, utilization and inference demand shape the next infrastructure cycle.
AI inference economics is moving beyond token pricing. A practical framework for measuring model cost, latency, utilization, reliability and business value at the workflow level.
 Alice
500 billion is …





