 admin
AI Inference Batching: The Hidden Trade-Off Between GPU Efficiency and User Latency
How inference batching improves GPU utilization while creating latency trade-offs, and how teams can tune batch size for interactive and background AI workloads.
How inference batching improves GPU utilization while creating latency trade-offs, and how teams can tune batch size for interactive and background AI workloads.
Compare vector retrieval and long-context models for enterprise AI across freshness, cost, permissions, latency, auditability and memory quality.
A production guide to AI agent observability across traces, tool calls, model outputs, permissions, latency, cost and failure analysis.
A practical guide to least-privilege permission design for enterprise AI agents that access tools, business data and action APIs.
Compare small and large language models for enterprise workloads across quality, latency, cost, privacy, deployment complexity and task specialization.
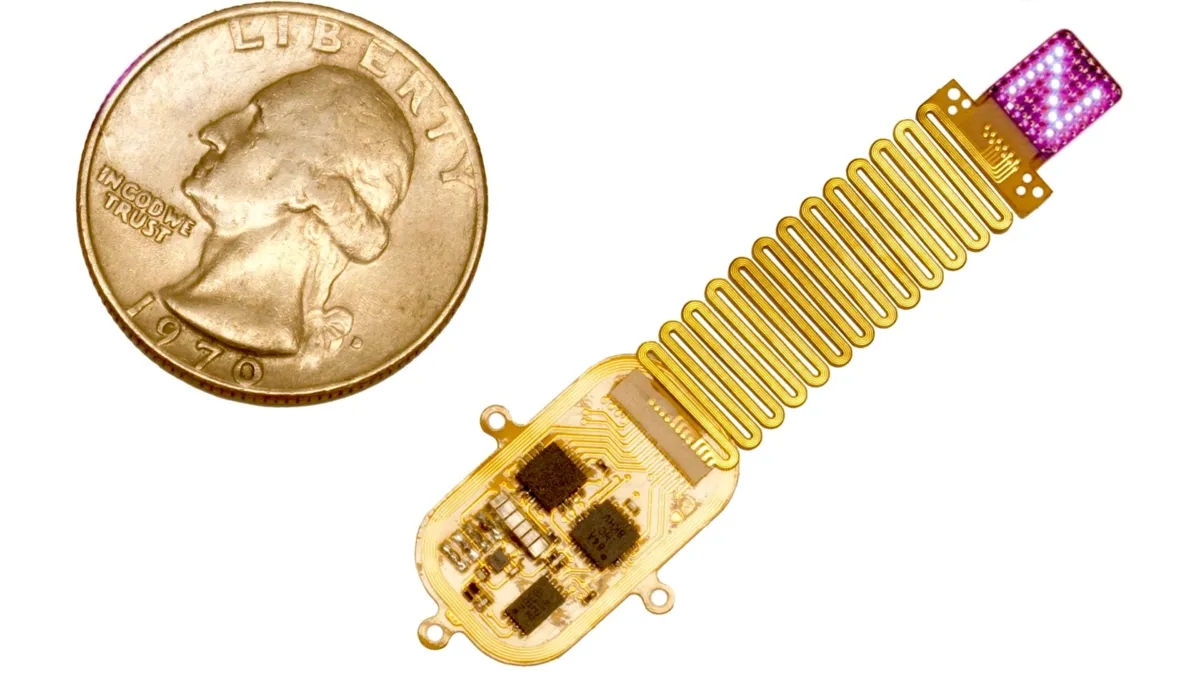
Source:Northwestern University…
As the sun sets in Tokyo, a yo…
Source:Cell Press “As sp…
 Alice
At 1 a.m., I shut down my lapt…
 Alice
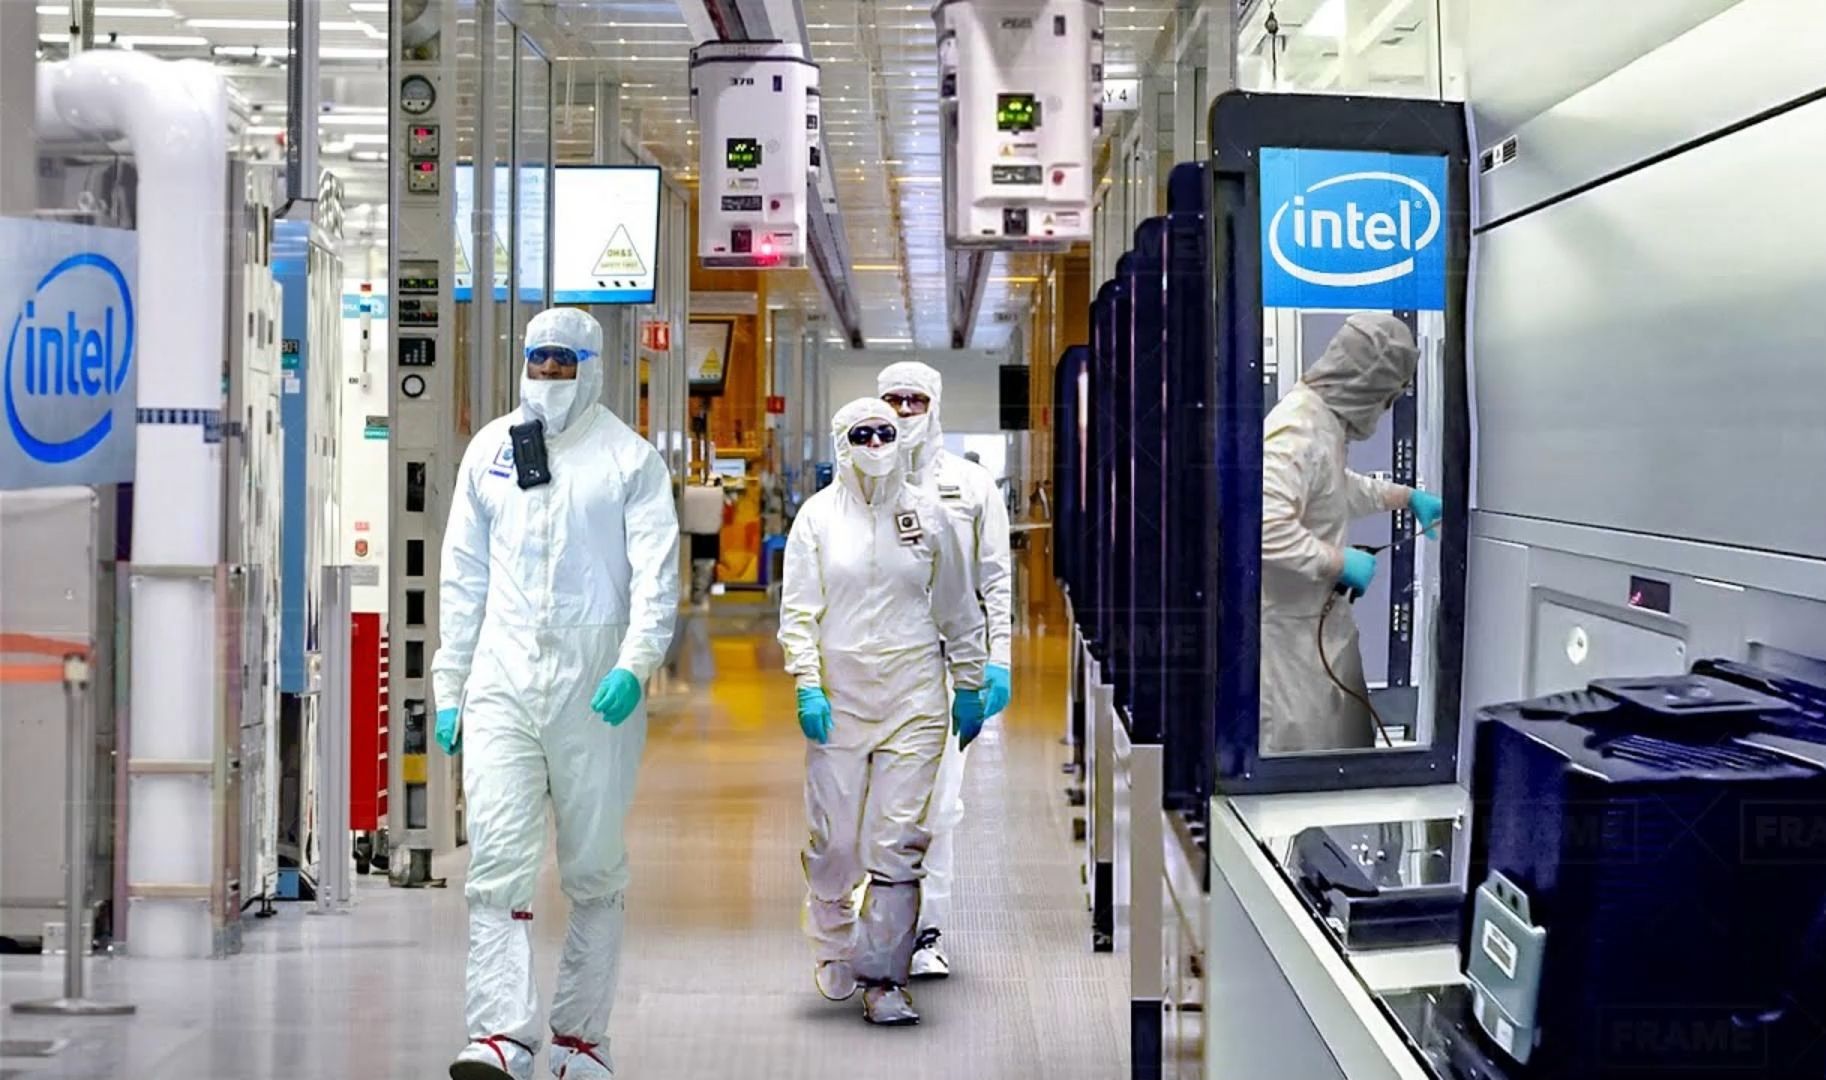
Over the past few years, Intel…





