Alice
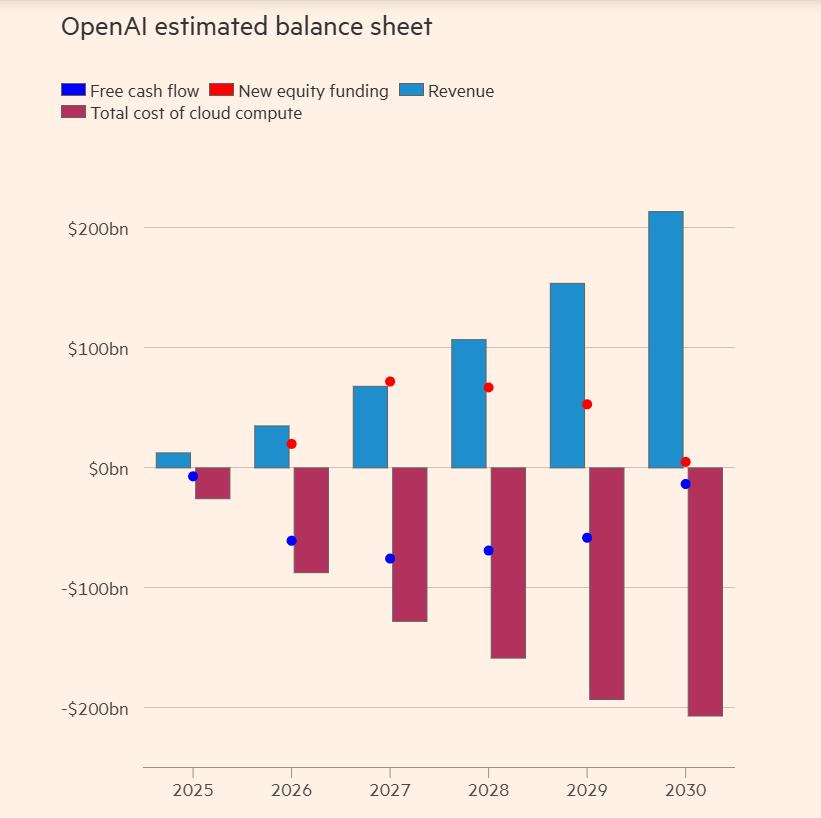
On November 27, it was reported that HSBC warned in its latest research report that even with explosive revenue growth by 2030, OpenAI will still face a funding gap of at least $207 billion. This figure not only highlights the soaring infrastructure costs and the intensifying market competition but also triggers profound concerns in the market about the sustainability of the entire AI ecosystem. Can this technology trend, characterized by soaring demand and unprecedented capital intensity, continue to operate smoothly?
Sky-High Computing Power Demand: The AI Foundation Built on Huge Leasing Contracts
The industry playfully describes OpenAI’s operational model as “a money-burning bottomless pit with a website as its facade,” and the demand for computing power is the direct cause of its financial black hole. HSBC’s U.S. software and services team updated its evaluation model for OpenAI, incorporating two key pieces of data: the 250 billion cloud computing resource leasing agreement that OpenAI signed with Microsoft in late October and the38 billion cloud services contract it reached with Amazon. These two major deals have boosted OpenAI’s total contracted computing power to 36 gigawatts.
Of 1.8trillion,OpenAIwillneedtopayapproximately620 billion annually in data center leasing fees in the future. What is concerning is that only about one-third of the contracted computing power is expected to be actually put into operation during this period. According to the report, from this year to 2030, OpenAI’s cumulative leasing costs will reach 792 billion. Looking ahead to 2033,the total computing investment commitment scould soar to1.4 trillion, a figure that coincides with the eight-year investment plan previously disclosed by OpenAI’s CEO, Sam Altman.
Instrument the end-to-end path
Measure queueing, execution, retries and final user outcome rather than only component health. Traces should make it possible to explain why a request was slow or wrong from the user’s perspective.
Version important configuration
Prompt templates, model routes and data dependencies can change behavior without code changes. Versioning these inputs makes regressions reproducible and rollback safer.
Prefer bounded failure
When dependencies degrade, reduce optional work or return a clear fallback instead of allowing latency and error rates to cascade through the whole system.
Define the production contract
Agree on expected quality, latency, cost and failure behavior before optimizing components. A service can look efficient in isolation while violating the user-facing objective.
Fallback and rejection behavior should be explicit so edge cases do not improvise at runtime.
Make state ownership explicit
Models, caches, queues and databases often hold overlapping representations. Each durable state should have one authoritative owner and a version so stale copies cannot silently win.
Test degradation and recovery
Simulate unavailable dependencies, stale caches and overload. A production system needs predictable fallbacks and a clear path back to normal operation rather than manual repair for every incident.
Instrument the end-to-end path
Measure queueing, execution, retries and final user outcome rather than only component health. Traces should make it possible to explain why a request was slow or wrong from the user’s perspective.
Version important configuration
Prompt templates, model routes and data dependencies can change behavior without code changes. Versioning these inputs makes regressions reproducible and rollback safer.
Prefer bounded failure
When dependencies degrade, reduce optional work or return a clear fallback instead of allowing latency and error rates to cascade through the whole system.
 admin