 Alice
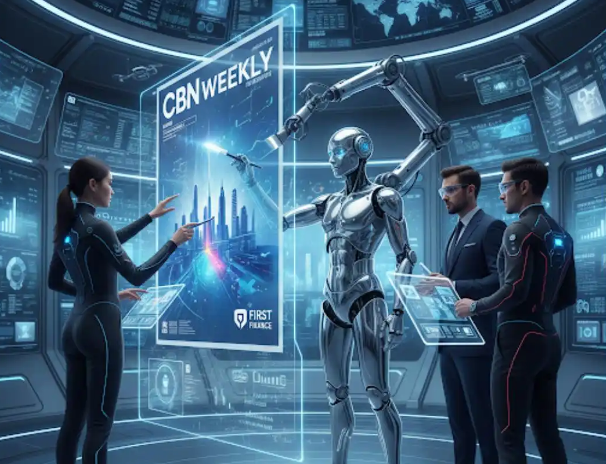
On November 20 (local time), shortly after Gemini 3 dominated the large model sector, Google unveiled another flagship product—Nano Banana Pro (Gemini 3 Pro for images). Users on social media worldwide have been enthusiastically experimenting with it, and numerous first-hand tests confirm significant progress in this model. Google stated that Nano Banana Pro leverages Gemini’s cutting-edge reasoning capabilities and real-world knowledge to visualize information more effectively than ever, such as creating and editing complex visual effects and infographics. Key upgrades of Nano Banana Pro include 2K/4K high-resolution direct output (critical for professionals), enhanced long-form text generation, multi-language support with in-image translation, adjustable shooting angles/focus/colors, flexible aspect ratios (1:1 to 9:16), and improved character consistency. Reporters from China Business Journal conducted two tests. While the Pro version shows marked progress over its predecessor, it still has flaws in detail handling. In the first test, the original Nano Banana generated incorrect magazine names and characters with extra limbs when creating futuristic newsroom scenes. The Pro version fixed the names and added barcodes but lacked clarity (likely due to being free). In the second test, following Google’s claim of multi-image fusion with character consistency, reporters input 5 photos (4 pets, 1 landscape). The output was a passable but underwhelming collage—no interaction between subjects/scenes, and one character was drastically altered, failing to maintain consistency.
Turn production failures into benchmark cases
Support incidents, user corrections and trace analysis reveal failure modes synthetic tests miss. Important incidents should be minimized into reusable cases and added to the regression suite before the next model or prompt change. Over time, the evaluation set becomes a memory of real product failures rather than a static research artifact. Separate quality, latency and cost.
A model can improve answer quality while becoming too slow or expensive for the intended path. Evaluate these dimensions separately, then apply product-specific release criteria instead of collapsing them into one opaque score.
Use repeated samples where variance matters
Non-deterministic systems need enough runs to distinguish a behavior change from ordinary sampling noise. One lucky completion should not decide whether a release ships. Define “better” before comparing candidates.
Model upgrades can change tone, tool behavior, latency and cost in addition to reasoning quality. Write the acceptance criteria before running the comparison so generic benchmark gains do not override product requirements. Different task classes may justify different model routes rather than one global winner.
Review evaluation-set edits like code
Adding or removing examples changes what the organization optimizes. Track the rationale, expected impact and version of each substantial change so historical trends remain interpretable. Connect offline metrics to live monitoring.
Use similar failure categories in production and evaluation where possible. This allows teams to see whether offline improvements reduce the real-world incidents they were intended to fix.
Record the full evaluation configuration
Dataset version, scoring logic, prompts, tools, retrieval state and model parameters all affect results. Store them together so a result can be reproduced rather than remembered as a single unexplained score. Benchmark changes should be versioned because changing the cases can move the metric even when the model does not. Keep a stable regression core.
A small set of critical product behaviors should run on every release, while larger experimental suites explore new capabilities. High-risk tool actions and safety boundaries can remain hard gates regardless of average score. This preserves comparability without freezing the entire evaluation program.
Analyze regressions by slice
Break results down by task type, language, context length, customer segment and risk class. Aggregate gains can hide serious failures in a small but important cohort. How to read the development beyond the headline.
The reported development is most useful when separated into confirmed facts, forecasts and interpretation. Product timelines, pricing, supply constraints, regulation and customer adoption can all determine whether an early headline becomes a durable shift. Readers should update the thesis as concrete follow-through appears instead of treating an initial announcement or market reaction as the final outcome.
What to watch next
Useful signals include shipped products, independently observed performance, customer commitments, pricing changes, financial guidance and regulatory decisions. Those indicators show whether the development is changing real operations rather than only sentiment. Second-order effects can matter more than the announcement.
Technology moves often affect suppliers, competitors, developers and customers as much as the company named in the headline. The practical question is whether the event changes cost, capacity, standards, distribution or strategic options. Long-term scenarios should be evaluated against near-term milestones so ambitious forecasts remain clearly separated from confirmed execution.

 admin




